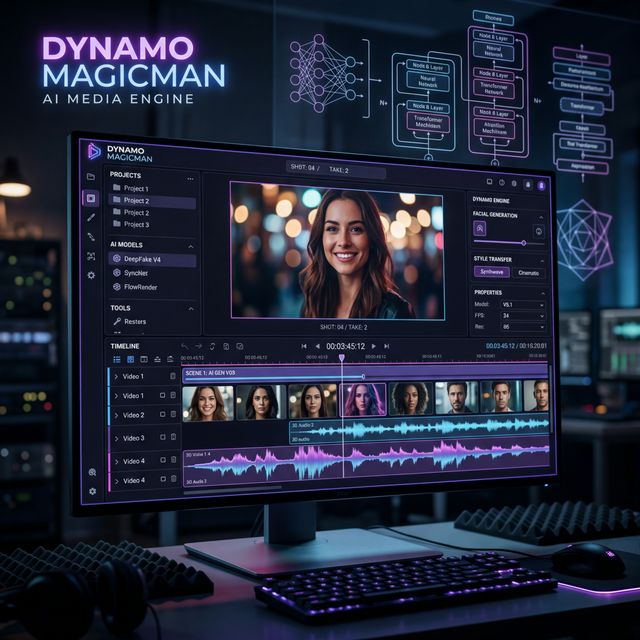
A unified 15B-parameter Transformer that jointly processes text, video, and audio via self-attention. No complexity, just pure creative power.
State-of-the-art performance in every dimension.
A unified 40-layer architecture that jointly processes all modalities via self-attention only. No cross-attention or multi-stream complexity.
Expressive facial performance, natural speech-expression coordination, and realistic body motion.
Native support for Chinese (Mandarin & Cantonese), English, Japanese, Korean, German, and French.
Generate a 1080p video in just 38 seconds on a single H100 GPU. Designed for production workloads.
How we built the world's most efficient media synthesis engine.
| Component | Description |
|---|---|
| 🥪 Sandwich Architecture | First and last 4 layers use modality-specific projections; middle 32 layers share parameters across modalities. |
| 🕐 Timestep-Free Denoising | No explicit timestep embeddings — the model infers the denoising state directly from input latents. |
| 🔀 Per-Head Gating | Learned scalar gates with sigmoid activation on each attention head for training stability. |
| 🔗 Unified Conditioning | Denoising and reference signals handled through a minimal unified interface. |
Proven results against industry leaders.
| Model | Visual Quality ↑ | Text Alignment ↑ | Consistency ↑ | WER ↓ |
|---|---|---|---|---|
| OVI 1.1 | 4.73 | 4.10 | 4.41 | 40.45% |
| LTX 2.3 | 4.76 | 4.12 | 4.56 | 19.23% |
| Dynamo MagicMan | 4.80 | 4.18 | 4.52 | 14.60% |
| Matchup | MagicMan Win | Tie | Opponent Win |
|---|---|---|---|
| vs Ovi 1.1 | 80.0% | 8.2% | 11.8% |
| vs LTX 2.3 | 60.9% | 17.2% | 21.9% |
| Resolution | Base (s) | Super-Res (s) | Decode (s) | Total (s) |
|---|---|---|---|---|
| 256p | 1.6 | — | 0.4 | 2.0 |
| 540p | 1.6 | 5.1 | 1.3 | 8.0 |
| 1080p | 1.6 | 31.0 | 5.8 | 38.4 |
Proprietary techniques driving absolute speed.
Two-stage pipeline: generate at low res, then refine in latent space, avoiding extra VAE round trips.
A lightweight re-trained decoder that substantially reduces decoding overhead for large batches.
MagiCompiler fuses operators across Transformer layers for a native ~1.2x speedup.
Enables generation in only 8 denoising steps without sacrificing final visual quality.